Automatic Whale Detection Using Deep Learning
Leveraging state-of-the-art deep learning techniques for automated whale detection.
Highlights
- Developed an automated whale detection model on Survey Data from Fisheries and Oceans, Canada (DFO)
- Tested different SOTA models like Deformable Detr, Yolov8, and backbones like VMamaba, ConvNext-T and Swin_T
- Systematically analyzed patch sizes (256–4096 pixels) and found patch size 4096 to be best
- Achieved an AP@IoU=0.1 of 0.878, using ConvNext with FasterRCNN
- Addressed domain adaptation challenges using active learning on new survey 2023 data
- Shipped the model into the production via Labelstudio and is currently used by DFO to annotate their new data
Dataset
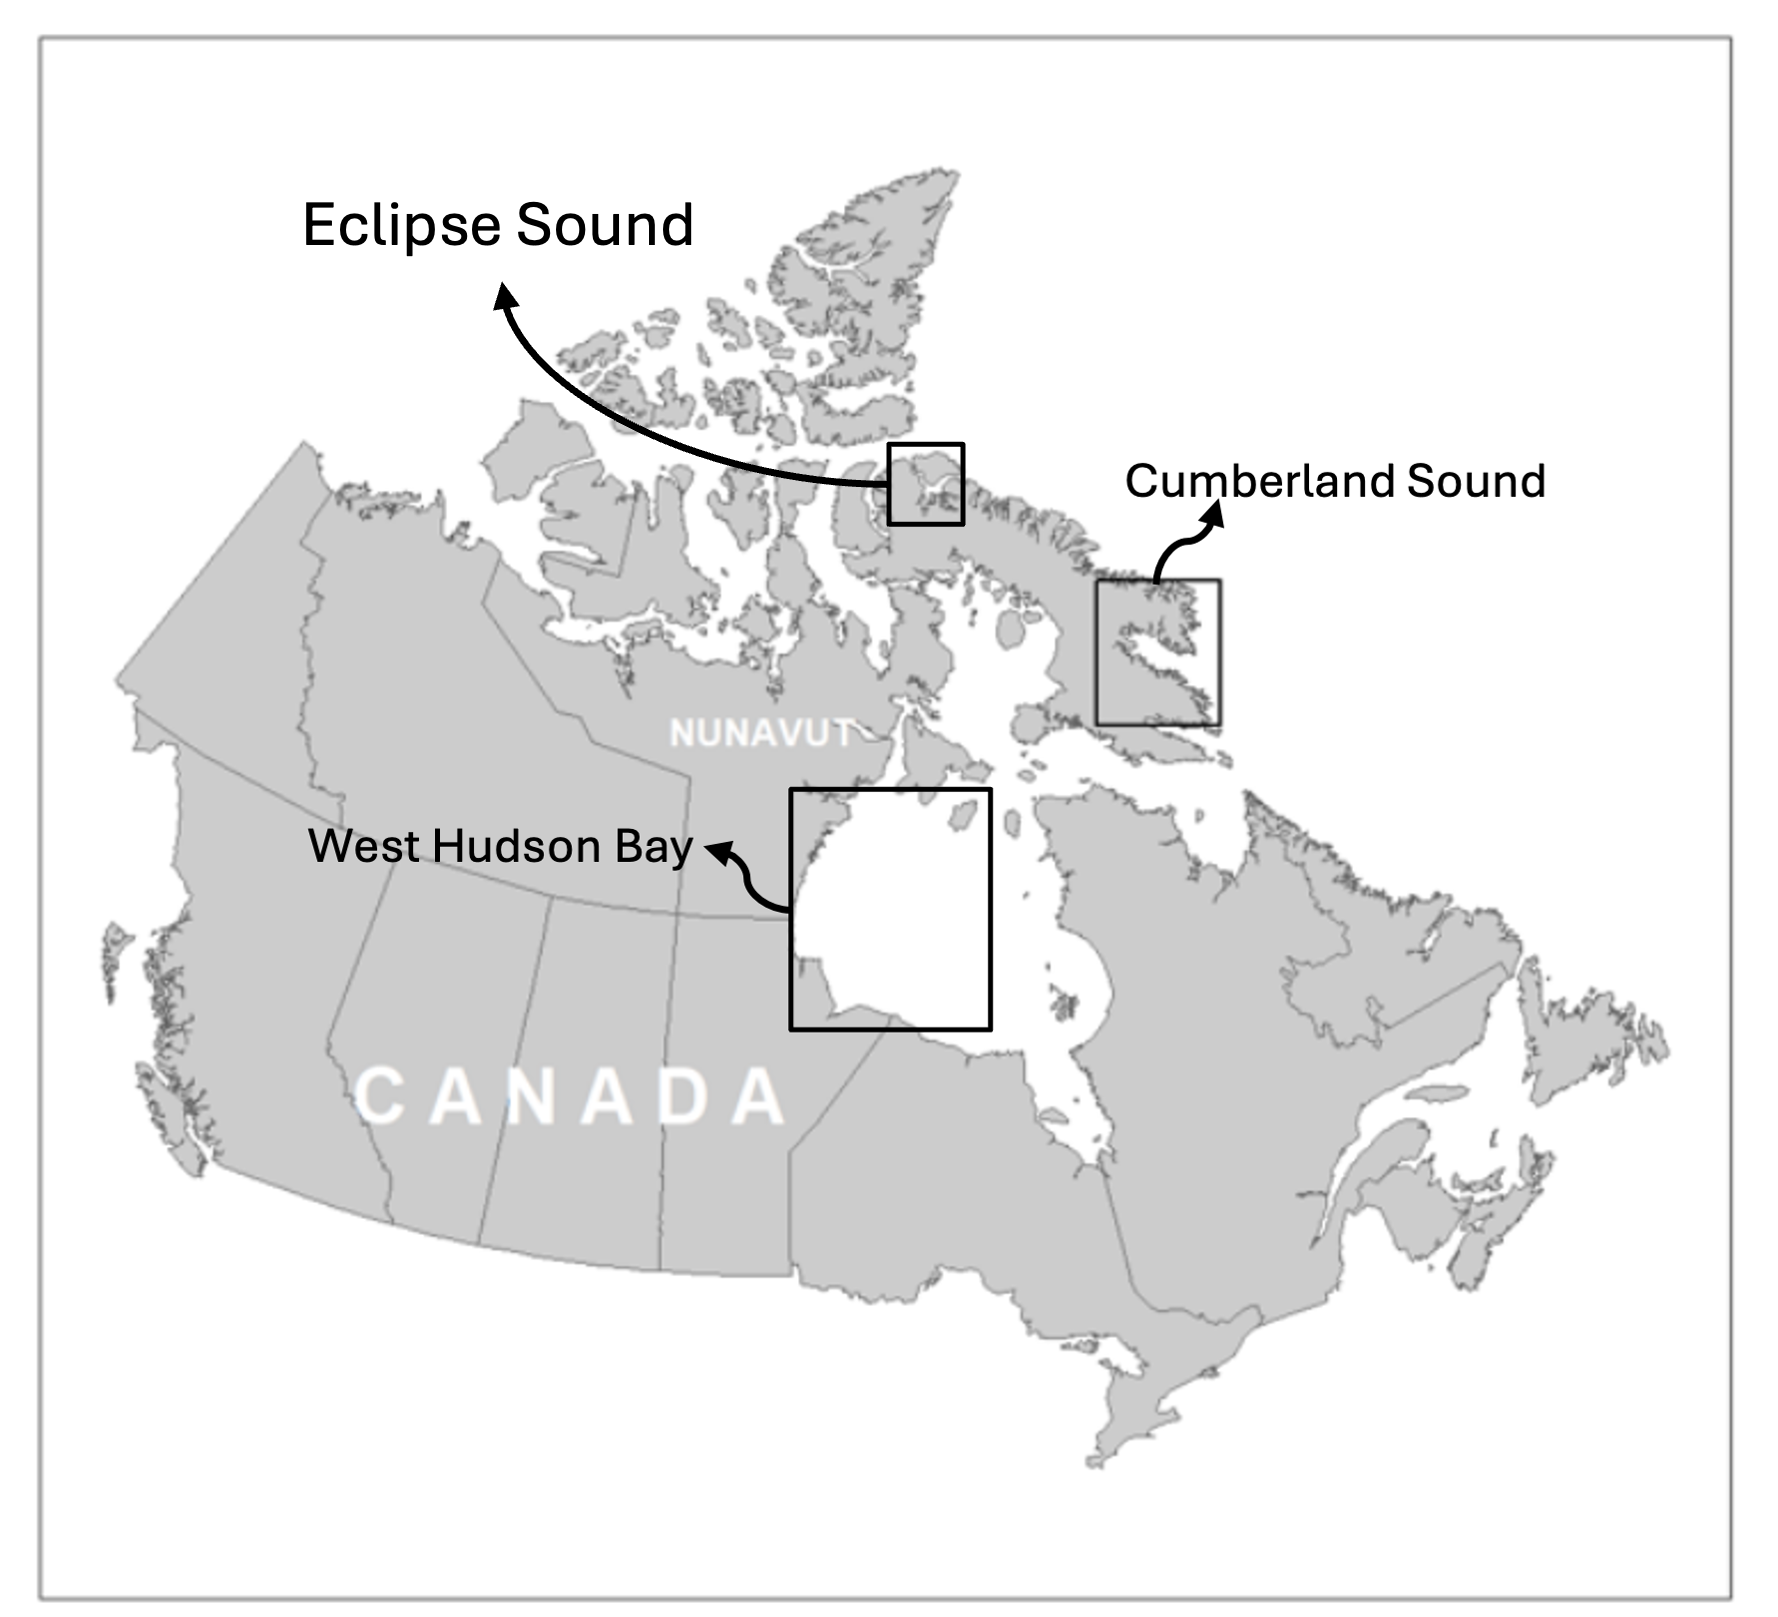
The dataset is collected over four different years(2014, 2015, 2016 and 2017) at Canadian Arcitc and contains two species: Beluga and Narval. The above figure shows the locations of survey. The dataset is particularly challenging because there is so much variability in the dataset. Factors such as time of day, wind speed, weather conditions, swell size, sediment, viewing angle, and water turbidity affect the visibility and appearance of the belugas and narwhals.
These images show the heterogeneous nature of the dataset. Prediction from the Best model is shown across datasets from different years. Click on individual images to zoom in. Click on the toggle button to show or remove prediction. Box color coding; TP: Green, FP: Red, FN: Blue.
The dataset, as illustrated in the above figures, contains significant background noise, including elements such as waves and sunglare that closely resemble the appearance of whales. Therefore context is really important when discerning whales other noises. The below figure illustrates the significance of contextual information in an image affected by sunglare.
Patches from size 256 to 4096. Orientation of the waves is critical to discern whales from waves.
Experimental design
First we start with three main family of objection detection architectures: FasterRCNN, YOLO and DeTr. Next we pair them up with 4 different backbone architecture namely: Resnet50, Swin-T, ConvNext-T and Vmamba. These backbones were chosen because of their varying receptive field. The below figure shows the receptive field of different backbone architectures.
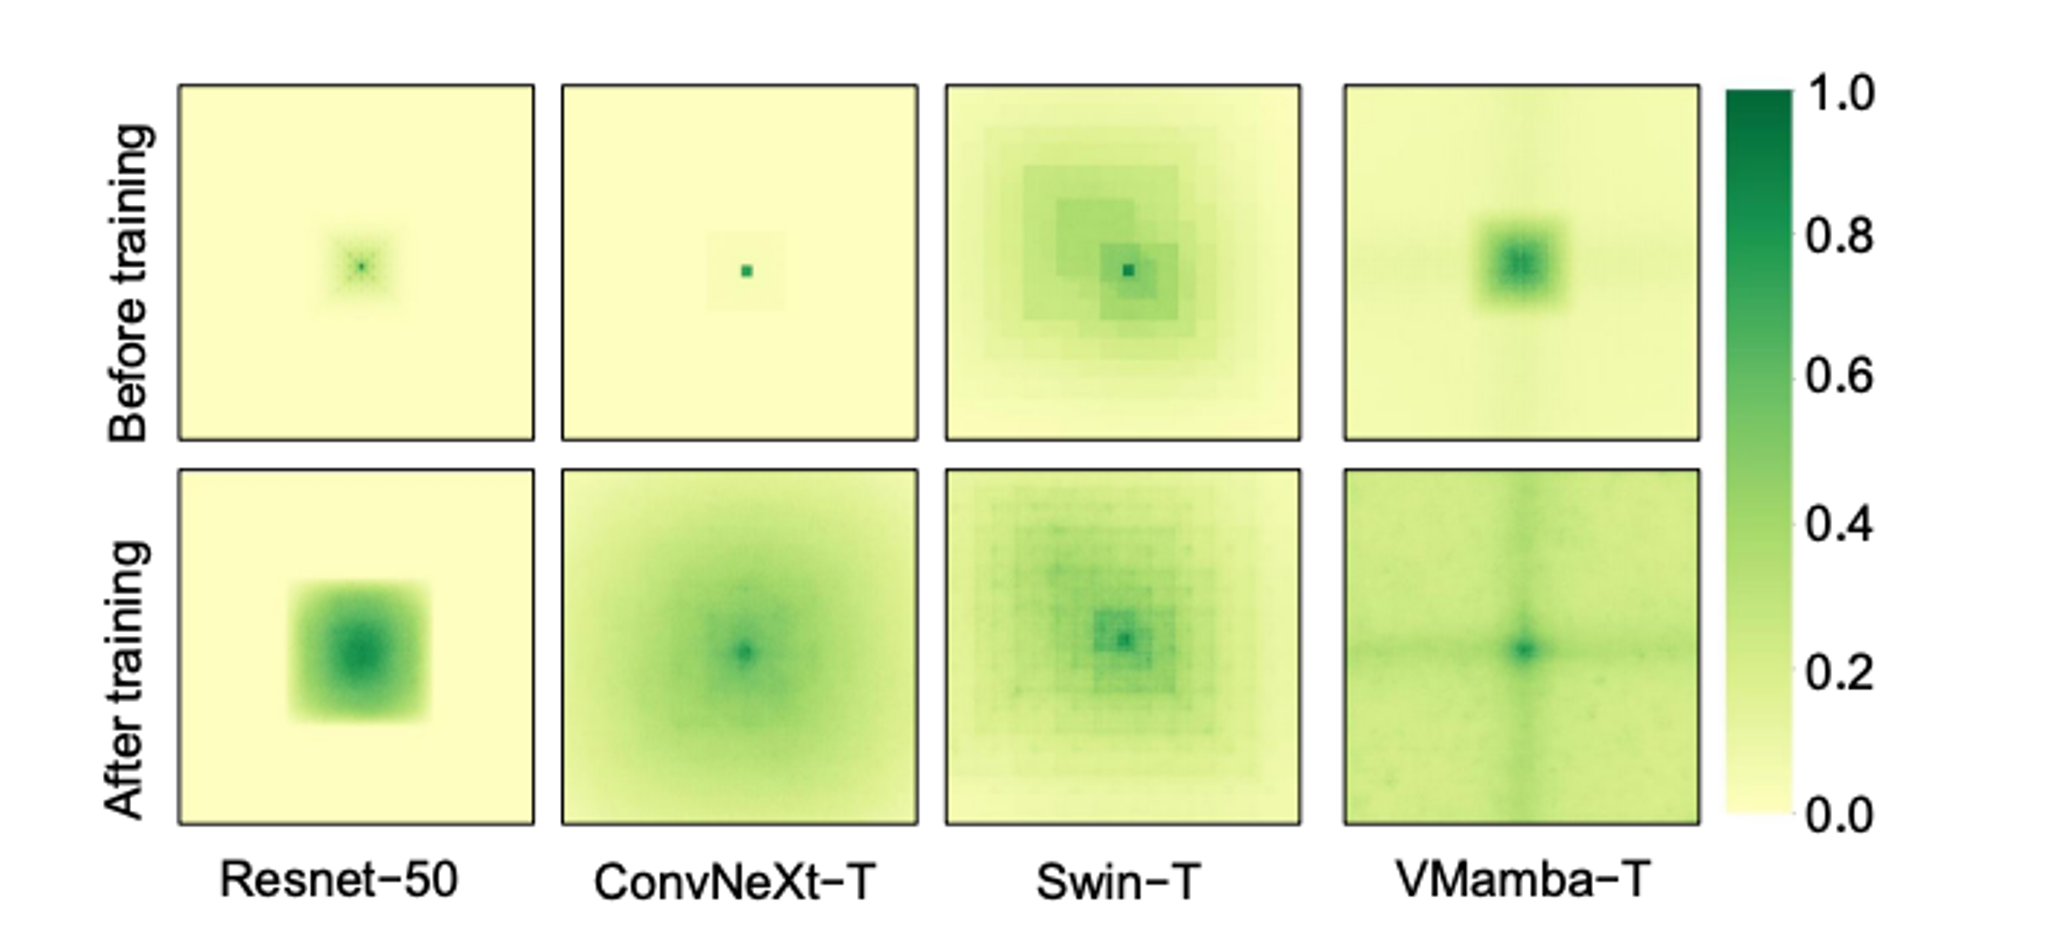
Effective Receptive Fields (ERF) between different backbone models. Figure adapted from Zhu et al., 2024, used under CC BY 4.0.
Therefore in the experimental design, we aim to:
- Determine the optimal patch size that balances contextual information and computational efficiency.
- Assess how different object detection models handle the complexities of whale detection in aerial imagery.
- Evaluate the effectiveness of various backbone architectures in extracting relevant features for whale detection.
- Identify the optimal configuration for operational deployment in marine mammal monitoring programs conducted by the DFO.
Result
The below table shows the \(mAP_{IoU=10\%}\) the performance of all the experiments. As can be seen the, FasterRCNN model, with ConvNext-T backbone performs best.
| # Params | Model | Backbone | Patch size 256 | Patch size 512 | Patch size 1024 | Patch size 2048 | Patch size 4096 | resize 50% |
|---|---|---|---|---|---|---|---|---|
| 40.10M | Deformable DETR | ResNet-50 | 0.794 | 0.820 | 0.847 | 0.761 | NP | 0.318 |
| 38.84M | Deformable DETR | Swin-T | 0.00 | 0.841 | 0.828 | NP | NP | NP |
| 40.80M | Deformable DETR | VMamba-T | 0.775 | 0.788 | LDC | NP | NP | NP |
| 39.15M | Deformable DETR | ConvNext-T | 0.812 | 0.833 | 0.832 | 0.741 | NP | NP |
| 41.35M | FasterRCNN | ResNet-50 | 0.746 | 0.810 | 0.833 | 0.843 | 0.840 | 0.663 |
| 44.75M | FasterRCNN | Swin-T | 0.793 | 0.841 | 0.863 | 0.860 | NP | NP |
| 46.71M | FasterRCNN | VMamba-T | 0.772 | 0.788 | 0.818 | 0.802 | NP | NP |
| 45.05M | FasterRCNN | ConvNext | 0.784 | 0.834 | 0.861 | 0.878 | NP | NP |
| 11.14M | Yolov8-s | Yolov8CSPDarkNet | 0.747 | 0.791 | 0.812 | 0.645 | NP | NP |
| 43.69M | Yolov8-l | Yolov8CSPDarkNet | 0.746 | 0.804 | 0.802 | 0.731 | NP | NP |
Adapting to new domain: Active learning
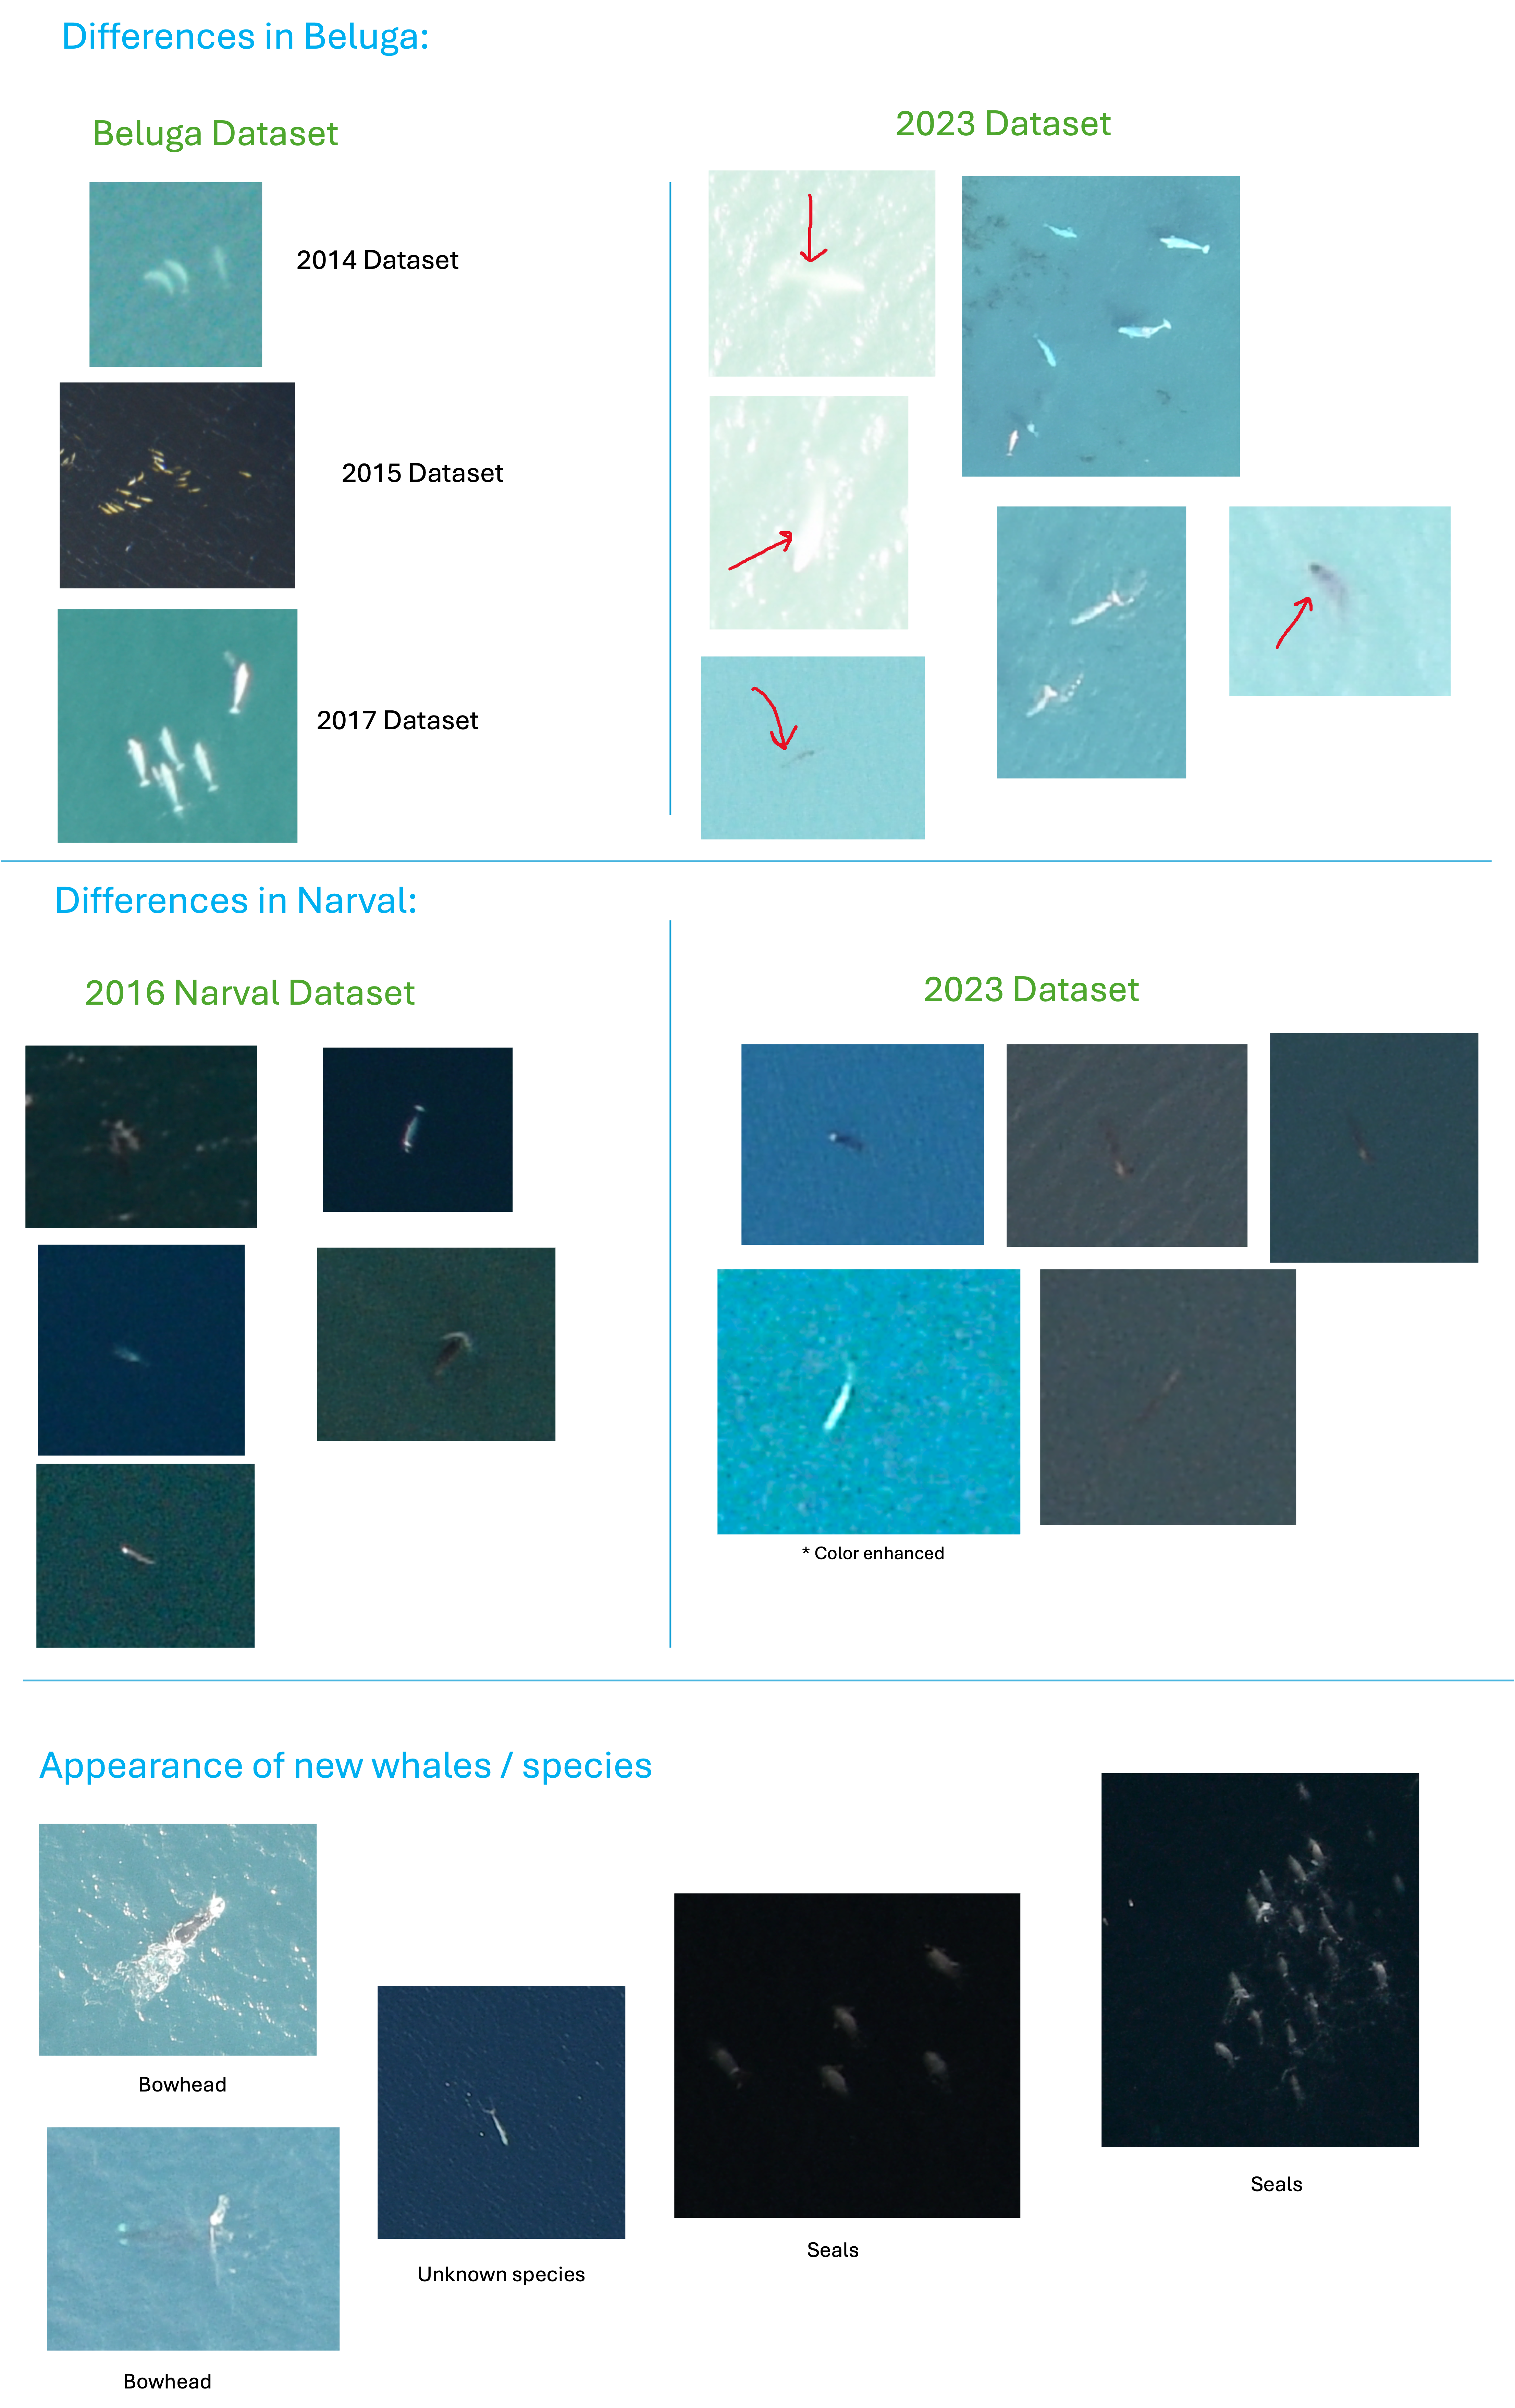
Differrences between old and new surveys.
In real world, the distribution of the dataset changes continuously. This happened with our partner, DFO in their newly captured survey. Their new survey contains images with ice, new species and different size of the whale. To address this, we use active learning which is a human-in-the-loop approach where few images are sampled from the unlabelled set such that the performance of the model will be maximized if trained on the new sample. We deploy this active learning pipeline using Labelstudio, where model’s prediction is continuously refined by a human annotator.
Below video shows an example image annotated and corrected using labelstudio. This workflow is moved into production and is currently utilzed by DFO for their annotation of the new survey.
Active learning: Result
The below table shows the evolution of the model after four active learning iterations
| AL iter | APIoU=10 | TP | FP | FN |
|---|---|---|---|---|
| 1 | 0.601 | 16 | 21 | 1 |
| 2 | 0.775 | 24 | 9 | 4 |
| 3 | 0.730 | 230 | 83 | 9 |
| 4 | 0.740 | 10 | 4 | 5 |
| Total | 280 | 117 | 19 |
The before and after results of finetuning the model is visualized in the below figure.
Left shows the model’s predictions before fine-tuning. Right shows the predictions after finetuning. Box color coding: Green, FP: Red, FN: Blue.
Thesis
I’ve published a thesis as a part of my Master’s program and the manuscript is available here.